S&P Global agreed on 17 September 2026 to acquire OpenZeppelin. Terms were not disclosed, the deal is subject to closing conditions, and S&P does not expect a material financial impact. OpenZeppelin keeps its name and runs as its own unit under co-founder and chief executive Demian Brener, who will report to Yann Le Pallec, president of S&P Global Ratings.
Almost every write-up framed this as a ratings agency buying an auditor. That undersells it. OpenZeppelin does not mainly review other people’s code, it writes the code other people use, and its libraries sit under more than $37 trillion in transferred value including most of the largest stablecoins and tokenised funds. S&P has not bought a reviewer. It has bought the author of the material it is about to start grading. The author nobody recused is the sixty-sixth unasked half of fairness.
TL;DR
- S&P Global is acquiring OpenZeppelin, whose open-source libraries underpin over $37 trillion in transferred value and which has run 900-plus engagements surfacing more than 10,000 vulnerabilities before code shipped.
- The plan is “the next generation of onchain security assessments, benchmarks, and essential intelligence”. S&P already publishes stablecoin stability assessments and rated its first DeFi protocol, Sky, in August 2025.
- Every critique of ratings since 2008 is about money: the rated party pays. This deal creates a conflict nobody has a rulebook for, which is authorship. The assessor wrote a large part of what it will assess.
- A money conflict is deliberate, so disclosure and firewalls address it. An authorship conflict is invisible to the person holding it: your own primitives are not a subject of review, they are the baseline review is measured against.
- Nobody publishes the figure that would let you price this: what share of an assessed codebase the assessor wrote, and whether inherited libraries were reviewed or merely trusted.
Credit first, and there is plenty of it
OpenZeppelin is not a badge mill. Founded in 2015, its contracts are the closest thing Solidity has to a standard library, they are in most of the largest stablecoins and tokenised funds, and they are in ours. Nine hundred engagements and ten thousand findings caught before production is not marketing, it is a decade of unglamorous work that prevented losses nobody will ever be able to count, which is the defining career problem of security review.
S&P is not a tourist either, and Le Pallec is honest about the ambition: “Our digital assets strategy centers on bringing trusted data, benchmarks, and transparent risk assessment to markets as they move onchain.” The thesis under the deal is correct, too. A project can have immaculate reserves, a strong credit profile and a spotless legal opinion, and still lose everything to one flawed function. Until now only one of those two risks had an institutional vocabulary, and building the second is a real service. So this is not the part where I tell you a ratings agency is about to ruin everything. The objection is narrower, and it survives all of that credit.
Everyone will reach for the wrong conflict
The reflex response to a ratings agency in crypto is issuer-pays, and it is the wrong thing to worry about here. Issuer-pays is a conflict of money: the rated party writes the cheque, the rater competes for the next mandate, grades drift upward. It is well understood, it has disclosure rules built around it, and it already exists on both sides of this deal, because protocols have always paid for their own audits and shopped for friendly ones.
The new conflict has nothing to do with money, and I have not seen anyone name it. The assessor wrote the thing being assessed. A grade covering code its issuer authored is not an independent opinion, it is a self-assessment in a third-party typeface. And this is not a hypothetical about one contract: if these libraries are in most large stablecoins and tokenised funds, a meaningful share of every future assessment is a verdict on code from the same building. Not reviewed by a sister team. Written there.
Why authorship is worse than money
A money conflict is intentional, which is what makes it tractable. You can disclose it, rotate the analyst, separate the fee from the finding, publish the methodology and let people discount accordingly. Everyone involved knows which way the pressure points.
An authorship conflict is invisible to the person carrying it, and no amount of integrity removes it. Your own primitives do not feel like a subject of review. They are the baseline review is conducted against, and nobody audits their own axioms, they audit deviations from them. So if a latent flaw is sitting in a widely used primitive, the party least likely to see it is the party that wrote it, has read it a thousand times, and has watched it work at $37 trillion of scale without incident.
That is not dishonesty, and it would be lazy to write this as though it were. It is epistemics, and it is harder to fix than corruption, because no ethics policy has a clause for “we stopped being able to see this part”. A conflicted analyst can be made to recuse. An analyst who cannot see the question does not know there is anything to recuse from.
The question nobody is being asked
So here is the unasked half, and it is a scope question rather than an accusation, because I do not know the answer and neither does anybody outside S&P. What share of the code covered by an assessment was written by the people doing the assessing, and does the document say so?
Nobody publishes that figure. Not S&P, not OpenZeppelin, not any audit firm, not any protocol. Find me an assessment that separates its findings by authorship, or one that says which inherited contracts were treated as reviewed and which were treated as trusted, because those are enormously different claims and the second is doing most of the work. Every answer the industry offers is about competence and price: hours spent, engineers assigned, methodology, who paid. None of it is about who wrote the material. The report tells you who commissioned the review. It does not tell you who wrote what was reviewed.
The risk a rating cannot express
There is a second-order version, and it lands on the product S&P sells. The purpose of a rating is differentiation: it tells you A carries different risk from B, so you can hold one and not the other. Now put the monoculture next to that. If A and B are built on the same primitives, the risk that hits them both at once is not expressible in a comparison between them. It sits underneath both, in the shared floor, and it will not show up in either grade however competently each is produced. You end up with a diversified-looking book of tokenised assets resting on one codebase, the correlation invisible precisely because the ratings are doing their job of describing differences.
And the assessor of both is the author of the floor.
The part where being on-chain did not help
Uncomfortable section, aimed at this blog as much as anyone. The libraries are open source, anyone can read them, and they are the most scrutinised code in the industry. That scrutiny is the honest reason they are good and the reason we use them.
But “battle-tested” is a claim about attention rather than correctness, and attention concentrates on exactly the code everyone has already decided is correct. Public source did not prevent this concentration, it caused it, because the rational move for any team is to inherit the reviewed thing rather than write a fresh one. That remains the right call, and I am not going to end this post telling anyone to roll their own crypto primitives, which is a reliable way to lose other people’s money. The point is narrower: transparency built the monoculture and transparency cannot price it. The next time anyone in this industry, us included, tells you code is safe because it is open and widely used, notice that both halves of that sentence are claims about popularity.
Every crypto casino already runs this experiment
Look at the trust row in any crypto casino’s footer. An audit logo, sometimes a PDF behind it. Here is the question that badge never answers: whose code did they actually look at?
A gaming contract is mostly inherited library plus a small amount of the operator’s own logic, and the operator’s part is where the odds, the payout curve, the entrant accounting and the house edge live. An audit that spends its pages on the inherited majority reads as thorough and says almost nothing about the part that can take your money. From outside you cannot tell the difference, because no report breaks findings down by who wrote what. And when the auditor wrote that inherited majority, the commercial incentive is to report on it warmly while the epistemic pull is not to report on it at all.
What Satoshie actually claims
Our claim here is narrow, and the first half is a confession: we are in the monoculture. Our contracts inherit these libraries like everyone else’s, and if a flaw is sitting down there we are exposed to it exactly as the tokenised funds are. Nothing in our architecture fixes that.
What we do not depend on is anybody’s opinion. The Chainlink VRF coordinator address is fixed in deployed code you can read before staking anything. Randomness is requested against a request ID, returned with a cryptographic proof, and that proof is verified on-chain before the callback may run. The verification is performed by code we did not write, against a key we do not hold, and re-executed by every node that validated the block. Our contracts on Base have no admin key, no upgradeable proxy, no owner function that can adjust odds and no pause switch to strand an in-flight draw, so changing a game means deploying a new address in public while the old one stays on chain as a record.
The property worth naming: nobody has to recuse themselves from that process, because nobody was asked their opinion. Recusal is a policy. Separation is a design. Policies are held by people who cannot see their own blind spots, which is the whole subject of this post.
Where this argument runs out
A VRF proof settles randomness and nothing else. It says nothing about whether our contract can be drained, whether the prize is funded, or whether our front end is showing you the game you think you are entering. Those are exactly the questions a security review answers, our contracts are not formally verified, and so we need precisely the kind of reviewers this post is about. This is not an argument against audits.
We have not read every line we inherit. Nobody has. We use these libraries because they are better than what we would write, and “everyone uses it” is the reasoning I have just spent a thousand words being suspicious of. The only difference I will claim is naming it rather than selling it as a strength.
Nobody rates us, and unrated is not a virtue. If S&P shipped a technology benchmark next quarter we would sit at the bottom for lack of coverage, not on merit. Criticising a grading system you have not been graded by is the cheapest move available, and I would rather name it than have you notice it.
Three questions
- What share of this codebase was written by the people who assessed it, and is that share stated anywhere in the document?
- Were the inherited libraries reviewed, or trusted? If trusted, on whose say, and would that party have been the one to find a flaw in them?
- When you tell me two rated products carry different risk, which of their shared components did that comparison actually cover?
S&P buying OpenZeppelin is probably good for this industry. Serious money is taking code risk seriously, and whatever vocabulary comes out of it will beat the one we have now, which is a logo in a footer. The thing to watch is not whether the assessments are competent. They will be.
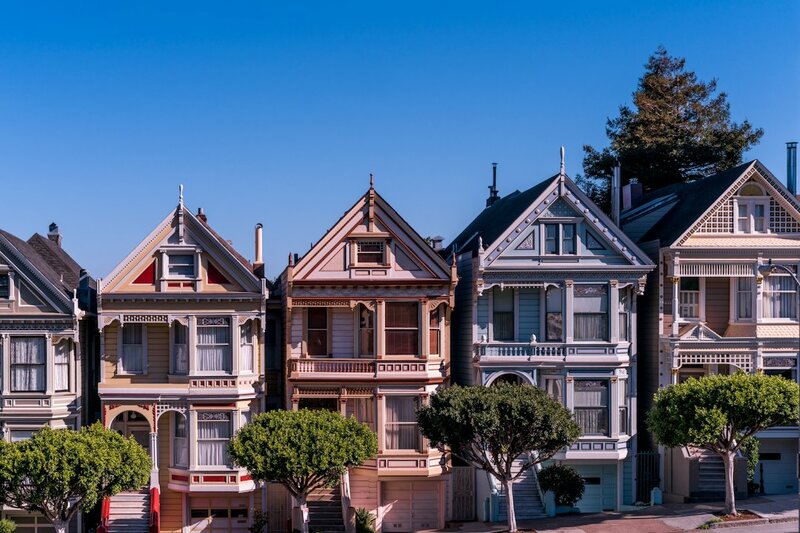
Five houses on a street can be told apart at a glance, and a surveyor can produce five honest reports explaining how they differ. It is a harder job when the same firm drew the plan they were all built from, and hardest of all when nobody thinks to ask.
📷 Photo by Cosmic Timetraveler on Unsplash